Sync Kernel Consulting
Backend performance consulting shaped like workshop craft — measured baselines, careful changes, and code paths you can defend in production.
We take scoped project work and ongoing technical advisory engagements for teams wrestling with latency, database contention, queue backlogs, and observability gaps.
How we work the metal, not the slide deck
Performance discovery sprints
Short, fixed-scope reviews of hot endpoints, SQL plans, cache hit rates, and worker pools — with flamegraphs and query traces you keep.
Implementation pairing
We pair with your engineers to land indexing changes, batching fixes, and back-pressure guards without surprise rollbacks.
Advisory retainers
Monthly office hours for architecture questions, release readiness checks, and capacity notes before traffic spikes.
Honest boundaries
We do not sell licenses, resell cloud credits, or promise ranking guarantees — only engineering time on your backend stack.
Stacks we commonly touch
PostgreSQL and MySQL tuning, Redis and Memcached eviction behaviour, Kafka consumer lag, gRPC/HTTP gateway timeouts, JVM GC pauses, and Go or Node service profiling.
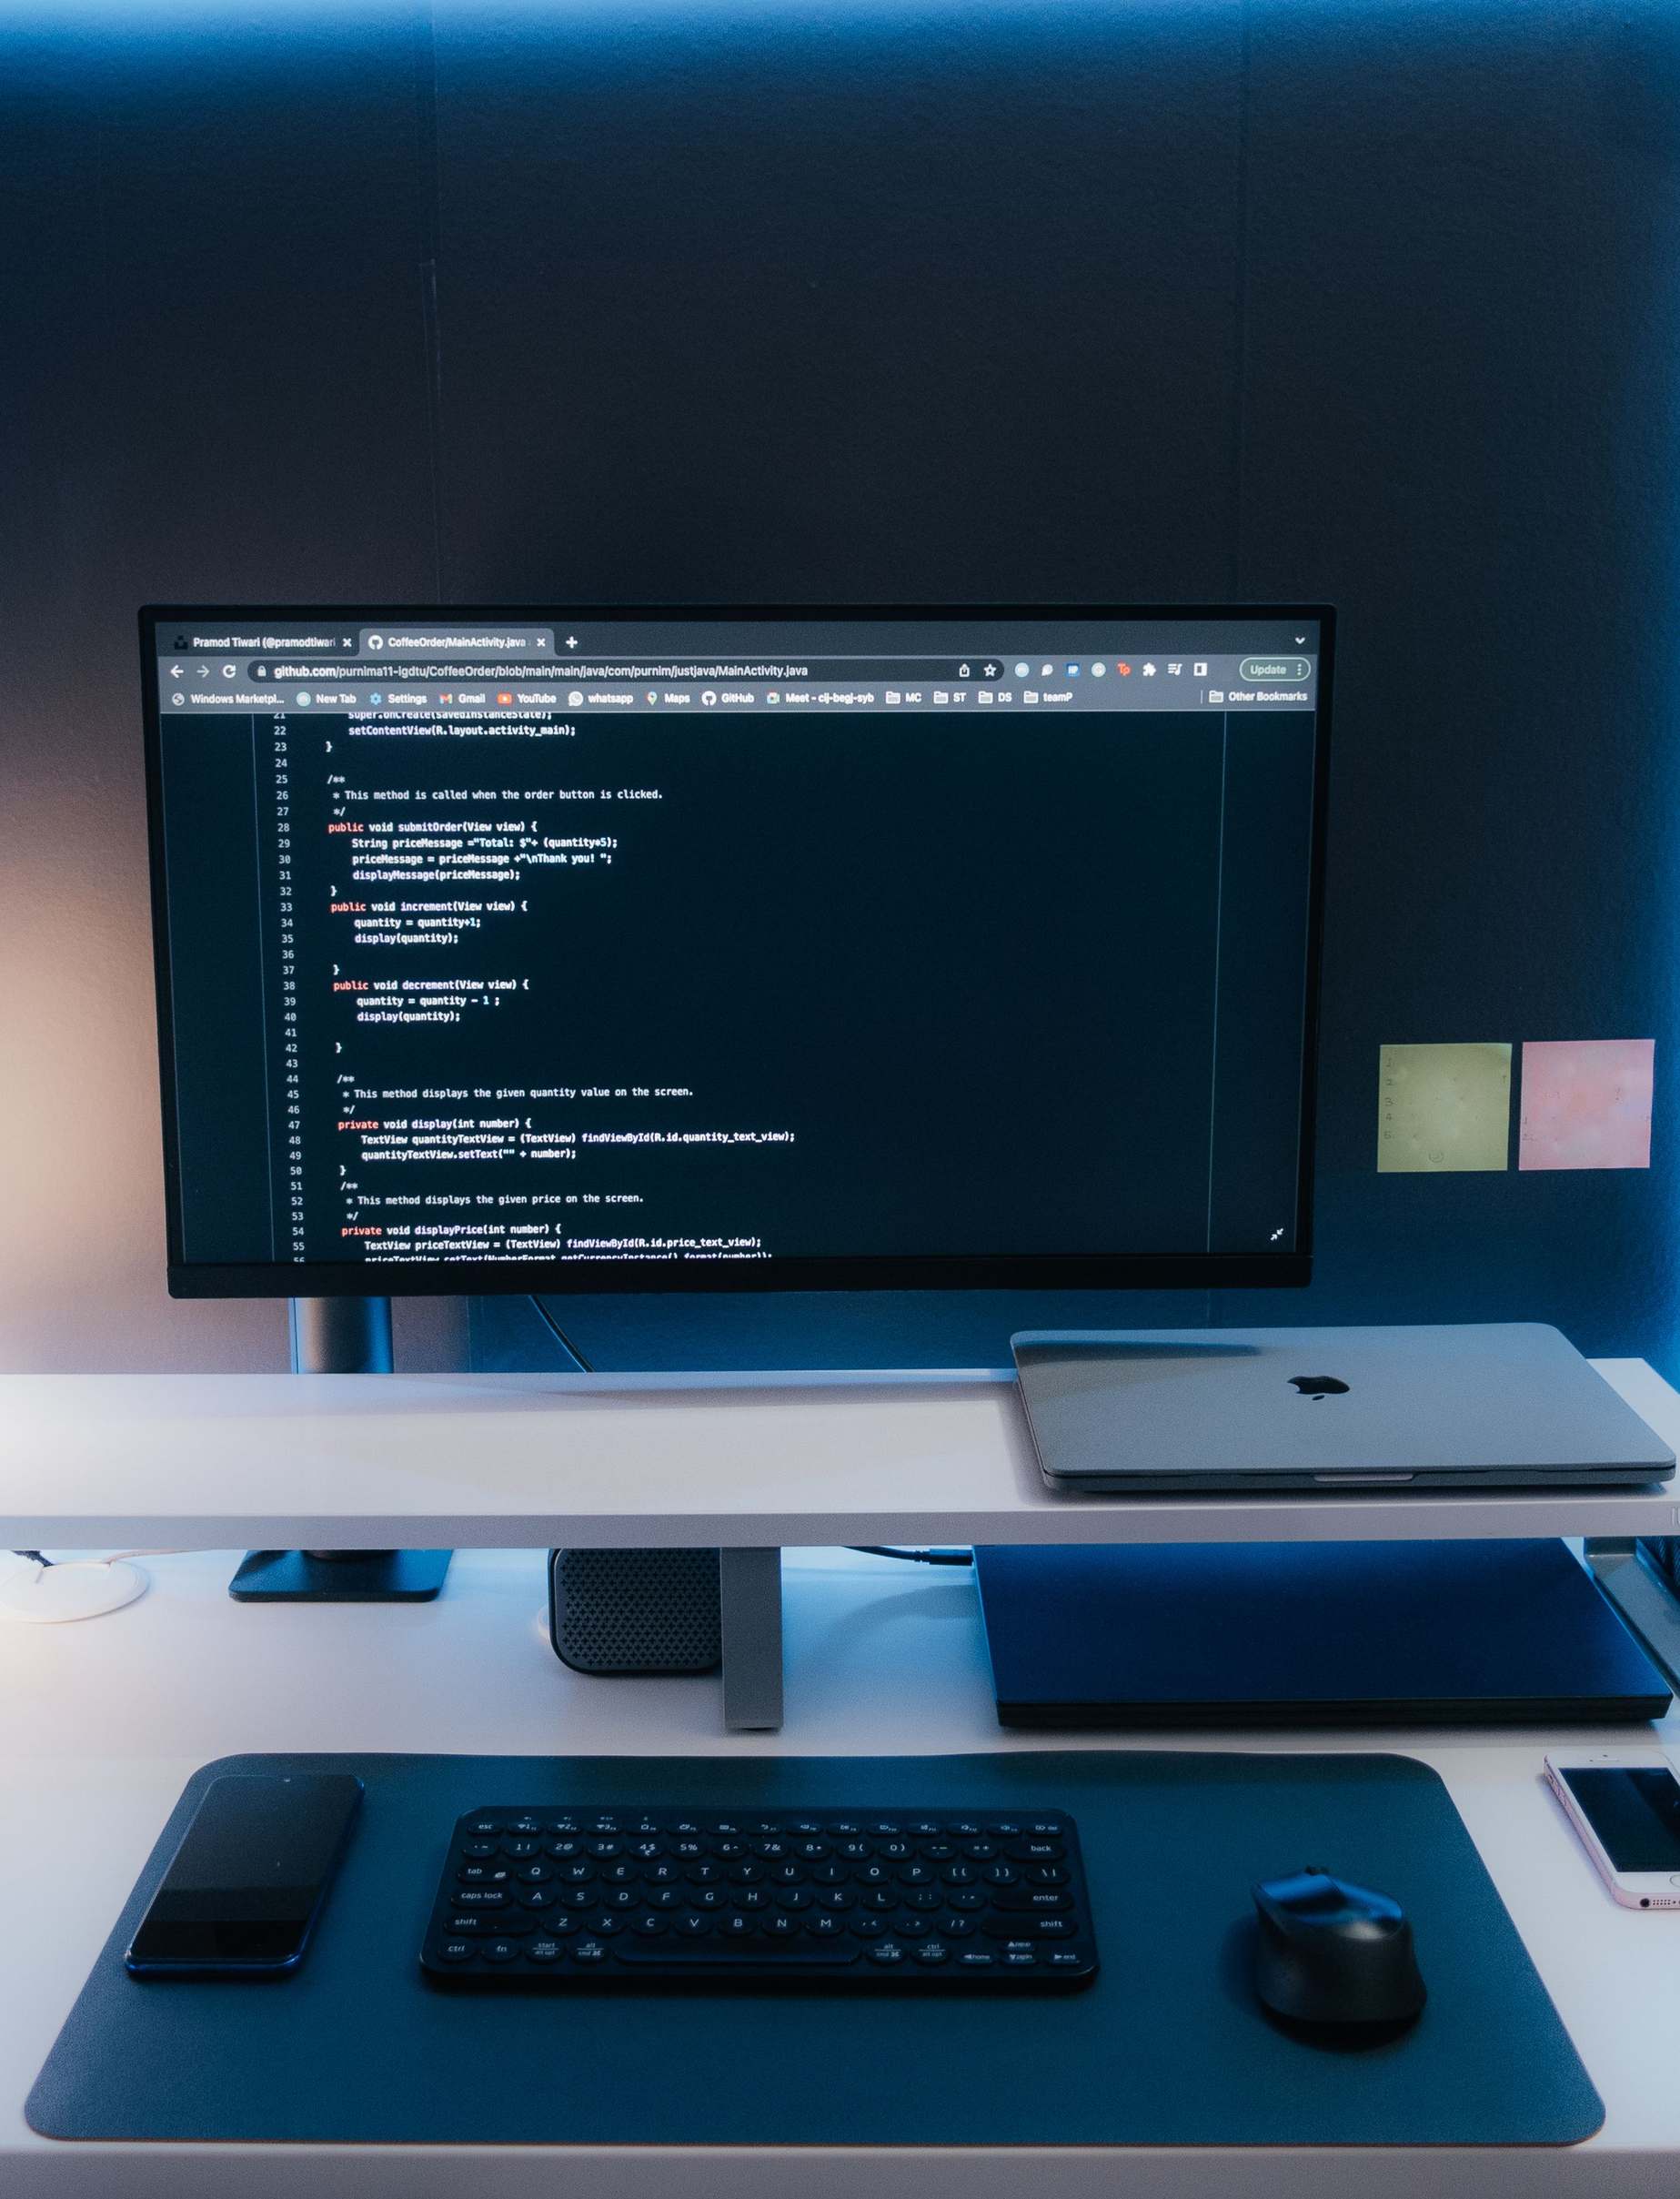
Trace first, tune second
Every engagement starts by capturing how requests actually move through your services — not how the diagram says they should.
We catalogue p95/p99 latency by route, lock waits, N+1 query patterns, and serialization costs before proposing changes. That discipline keeps recommendations tied to your codebase instead of generic “add caching” advice.
When we suggest a change, you get a rollback note and a verification checklist so your on-call team knows what to watch after deploy.
Performance work is carpentry: shave only where the grain shows stress, and leave joinery that survives the next season of traffic.
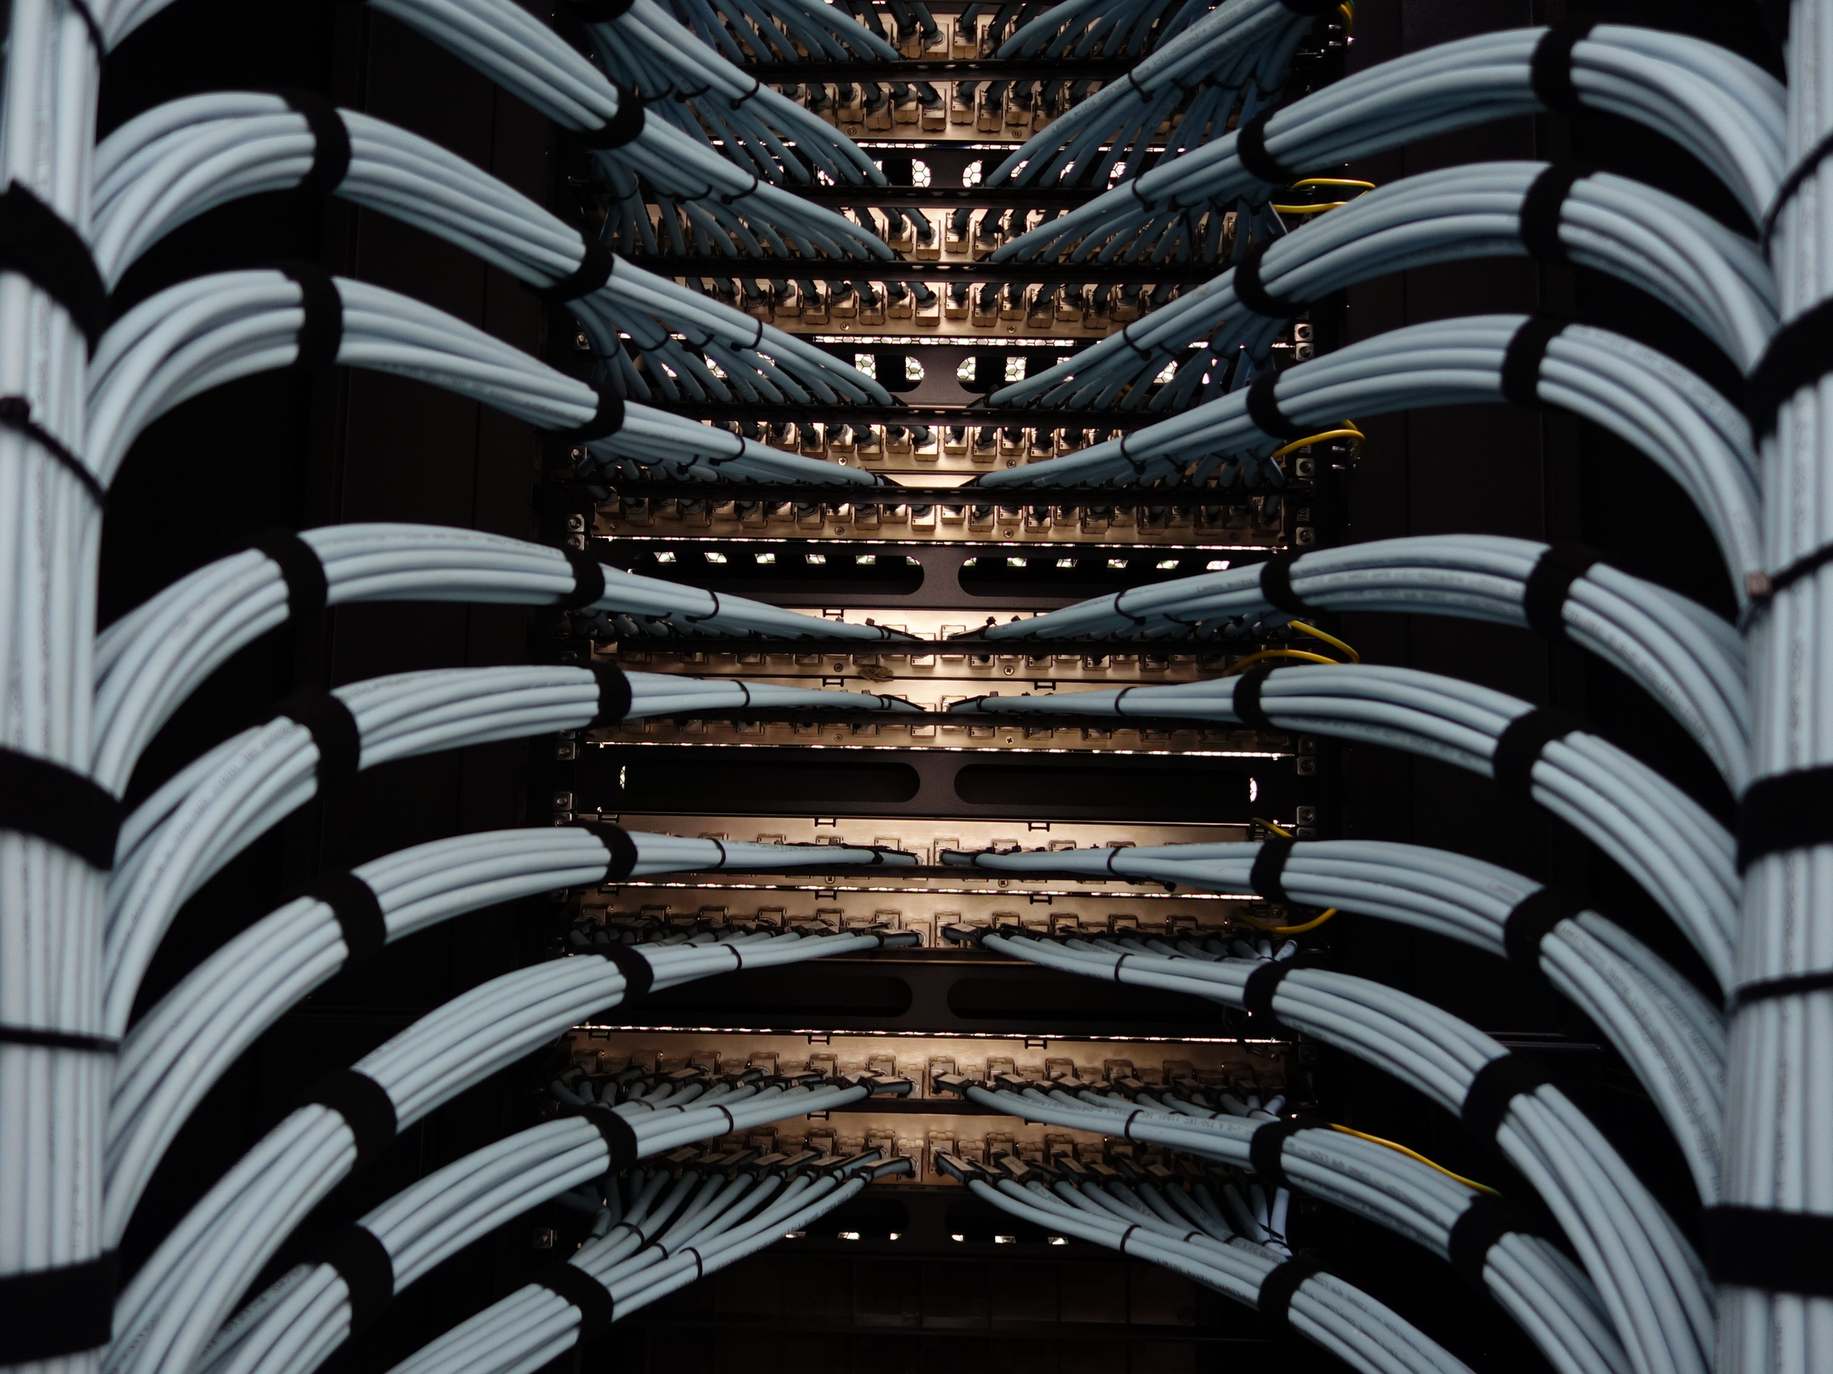
Inside the rack
Cable discipline and query discipline share the same rule — messy paths hide failures until load arrives.
Questions teams ask before booking
- Do you embed with our repo? Yes for implementation scopes — read-only access is enough for discovery; write access is agreed per milestone with your security team.
- Can you work with our existing APM? We ingest OpenTelemetry, Datadog, New Relic, or self-hosted Prometheus/Grafana; the goal is one timeline everyone trusts.
- What does advisory cover? Architecture reviews, load-test planning, incident postmortems focused on backend bottlenecks, and second opinions on vendor RFPs — billed as prepaid hours.
- Where are you based? We operate from Kuala Lumpur, Malaysia, with remote sessions across ASEAN time zones.
Dashboards inform the work; they do not replace reading profiles and slow query logs.
Ready for a scoped conversation?
Share your stack, traffic shape, and the symptom you need solved — we reply with whether a discovery sprint or advisory block fits.
Send an inquiry